The Comprehensive Guide to Understanding IT Incidents

In a landscape where technology underpins nearly every aspect of business, IT systems play a critical role in ensuring smooth operations.
However, what happens when something goes wrong? When systems fail or services are disrupted, businesses face what's commonly known as an incident. For someone who is not technical, the idea of an IT incident can seem scary. However, it is a simple and organized process when explained clearly.
This guide will help you understand IT incidents, how teams manage them, and how their impact is communicated to businesses. By the end, you'll have a clearer picture of how incident response and incident management keep IT wheels turning smoothly.
What is an Incident?
Before diving into the nitty-gritty, let's start with the basics.
In the IT world, an incident is any unplanned disruption to a service or a degradation in its performance. It could be as minor as a user being unable to access their email or as severe as a data center outage impacting thousands of customers.
What sets an incident apart is its urgency—it needs to be resolved as quickly as possible to minimize its impact on users and businesses. At its core, an incident is an unplanned disruption to an IT service or a failure in its operations.
Imagine using an app that suddenly stops working or a website that crashes just as you're about to complete an important purchase. These disruptions, whether small or large, are examples of incidents.
Common Types of IT Incidents
IT incidents generally fall into a few recognizable categories:
- Software incidents: Application crashes, failed deployments, or bugs that disrupt normal functionality.
- Hardware incidents: Server failures, disk crashes, or failing network equipment.
- Network incidents: A website going offline, a sudden network slowdown, or connectivity loss between systems.
- Security incidents: Unauthorized access attempts, malware infections, or data breaches.
- Human error: Misconfigurations, accidental deletions, or incorrect changes pushed to production.
- Communication and service incidents: Email servers failing to send or receive messages, or a service integration silently failing.
Some of these overlap in practice. For example, a hardware failure can trigger a network incident, and a misconfiguration (human error) can cause a security incident. Categorizing an incident correctly is part of what determines who it gets routed to and how it's prioritized.
The Lifecycle of an IT Incident
Now that we've identified what incidents are, let's look at how IT teams approach them systematically. Resolving incidents isn't just about fixing a problem; it's about following a structured process to ensure nothing is overlooked.
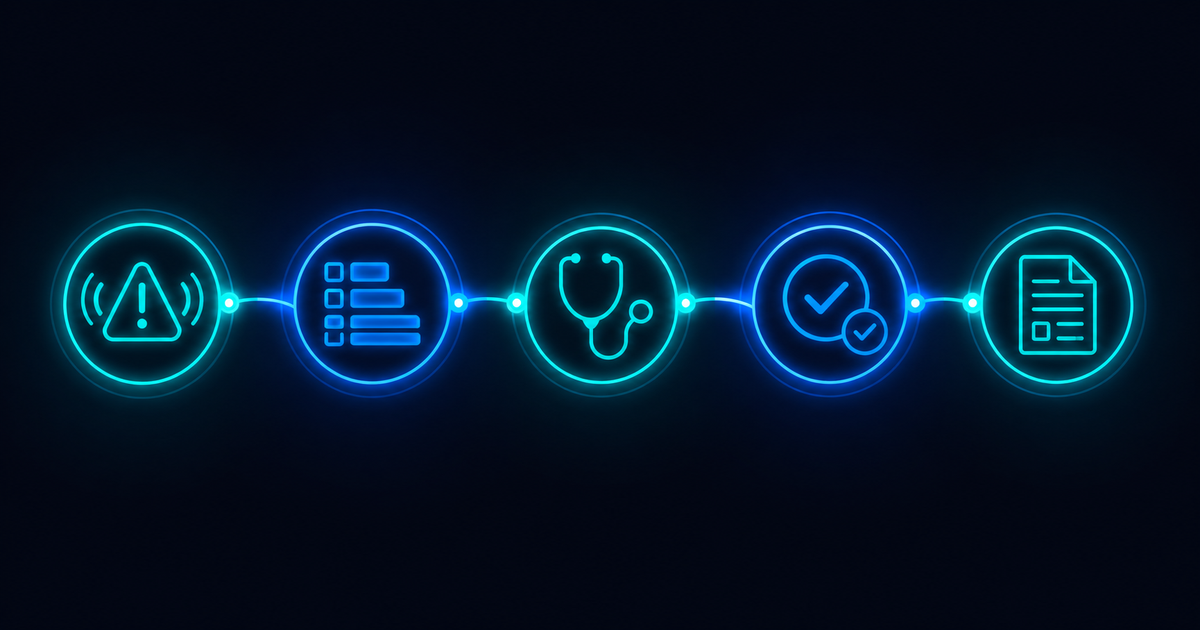
Every incident follows a lifecycle that guides IT teams from detection to resolution. This structured approach ensures efficiency and accountability in handling disruptions:
1. Incident Detection and Reporting
Incidents are often first detected through automated monitoring tools or by end-users reporting a problem. For example, a website crash might trigger an alert to the IT team, while an employee might submit a ticket about being unable to log into their system.
Why it matters: The faster an incident is detected, the quicker the response time—and the lesser the disruption.
2. Classification and Prioritization
Once detected, the incident is classified based on its severity and scope. Teams assess:
- Impact: How many users or systems are affected?
- Urgency: How quickly does this need to be addressed?
For instance, a server outage affecting the company's main website will likely be prioritized over a single employee's printer issue.
Why it matters: This step ensures that the most critical incidents receive immediate attention, preventing further business disruptions.
3. Investigation and Diagnosis
At this stage, IT teams analyze logs, use diagnostic tools, and perform root cause analysis to determine the source of the problem. For example, a slow application might point to a database overload or a misconfigured server.
Why it matters: Pinpointing the cause is essential for applying the correct fix and preventing recurrence.
4. Resolution
With the cause identified, the next logical step is resolution. Let's explore how teams move from diagnosis to recovery.
This is the action phase. IT teams apply the necessary fix, whether that's restarting a server, rolling out a software patch, or blocking malicious activity.
Resolution typically follows one of two paths:
- Workaround: A temporary measure that restores service without addressing the underlying cause. Workarounds get users back online fast but leave the incident open until a permanent fix is applied.
- Permanent fix: A change that resolves the root cause directly, closing the incident for good rather than deferring it.
Once a fix is applied, teams verify that systems are fully functional before considering the incident resolved—checking that the affected service is not just running again, but performing as expected under normal load.
Example in Action: If a network outage disrupted communication tools, restoring the connection is the workaround; identifying and correcting the misconfigured switch that caused it is the permanent fix. Only the second step actually closes the incident."
5. Communication, and Documentation
While technical teams work on solutions, other team members keep stakeholders informed. Updates might be shared through emails, dashboards, or even press releases, depending on the incident's impact.
Why it matters: Transparency builds trust and keeps everyone aligned on progress, reducing panic during critical incidents.
Documentation and Closure
Once resolved, the incident is documented in detail. This includes:
- What caused the incident.
- Steps taken to resolve it.
- Recommendations for preventing similar incidents in the future.
This documentation serves as a knowledge base for future incidents, enabling faster resolutions and continuous improvement.
IT Incidents Impact Businesses!
We've seen the lifecycle of an incident. Now it's time to zoom out and explore how these incidents affect businesses and how IT teams work to minimize their impact.
When an incident occurs, it's not just an IT problem—it's a business problem. Downtime or service disruptions can have far-reaching consequences.
- Financial Losses: Every minute of downtime can result in lost sales or productivity.
- Reputational Damage: Customers may lose trust in a brand if services are unreliable.
- Operational Delays: Teams may be unable to meet deadlines or perform critical tasks.
Just to name a few.
Think of an online shopping platform crashing on Black Friday. The financial and reputational impact could be devastating.
To mitigate these effects, organizations rely on robust incident management strategies.
The Role of Incident Management
Incident management is the ongoing discipline that keeps the incident lifecycle running smoothly, incident after incident. Where the lifecycle describes what happens to a single incident, incident management is the set of practices, tools, and ownership that make that process repeatable at scale - proactive planning, efficient communication, and constant improvement.
Incident Management vs. Problem Management
Incident management and problem management are often confused, but they solve different problems. Incident management focuses on restoring service as quickly as possible, regardless of the underlying cause. It's reactive by design. Problem management picks up after the incident is resolved, investigating the root cause to prevent that same incident from recurring.
In practice, a recurring incident (for example, the same server crashing every few weeks) is a signal that incident management alone isn't enough. That pattern is a problem management responsibility: finding and fixing the underlying issue rather than resolving the same incident repeatedly.
Proactive Monitoring
Modern IT teams use tools that detect anomalies before they escalate into full-blown incidents. For example, monitoring software can flag unusual spikes in server load, allowing teams to act preemptively.
Automation in Incident Management
Automation simplifies incident response by:
- Automatically categorizing incidents.
- Assigning them to the right teams.
- Triggering preconfigured solutions for common problems.
Automation doesn't replace incident management—it removes the manual overhead from the parts of the process that are repetitive and rule-based, so teams can focus on the incidents that actually need human judgment.
A Day in the Life of Incident Management
Picture this: An e-commerce platform experiences a sudden outage during a peak sales hour. Here's how an optimized incident management system handles it:
- Monitoring tools detect the issue and send alerts to the IT team.
- The incident is classified as critical and automatically assigned to the infrastructure team.
- While automated workflows attempt to restart services, customers are notified of the disruption.
- The root cause (a server misconfiguration) is identified and resolved within minutes.
- The incident is documented, and a post-mortem analysis prevents recurrence.
This seamless coordination minimizes downtime, maintains customer trust, and keeps business operations on track.
Conclusion
Incidents may be inevitable in IT, but their impact doesn't have to be catastrophic. By understanding how they are detected, managed, and resolved, businesses can ensure that disruptions are minimized, and systems remain resilient.
Whether you're a technical expert or a curious beginner, grasping the basics of incident response and management empowers you to appreciate the behind-the-scenes efforts that keep the digital world running smoothly.
Frequently Asked Questions
What Problems Does Incident Management Software Solve?
Incident management software centralizes detection, categorization, assignment, and tracking so incidents don't get lost across email threads or spreadsheets. It reduces response time by routing incidents automatically and gives teams a documented history to spot recurring patterns.
How Does Cybersecurity Incident Response Differ From General IT Incident Management?
Cybersecurity incident response focuses specifically on security events (breaches, malware, unauthorized access, etc.) and typically involves containment, evidence preservation, and compliance reporting alongside resolution. General IT incident management covers the full range of service disruptions, most of which aren't security-related.
When Should Incidents Be Escalated?
Incidents should be escalated when the assigned team lacks the access, expertise, or authority to resolve it, when the incident's impact grows beyond its initial assessment, or when resolution time exceeds agreed service levels.
What Causes Long IT Incident Resolution Times?
Common causes include unclear ownership, incidents bouncing between teams before reaching the right owner, missing diagnostic information at handoff, and a lack of documented playbooks for recurring incident types.